
An offline assistant for Indian digital fraud
Seerie is a compact, on-device language model that helps people in India recognize, respond to, and report digital fraud, including UPI scams, OTP and KYC fraud, digital arrest, fake jobs and notices, fake donation appeals, online “friends” who ask for money, and almost 3,000 other scam topics. It runs fully offline, so user questions and personal data never leave the device.
This page points to GGUF quantizations of Seerie v3 for llama.cpp, Ollama, and LM Studio: seerror-technologies/seerie-v349-GGUF. The previous model (v2, dataset v224) remains at seerror-technologies/seerie-v224-GGUF. The Seerie app is live on Google Play. Install links also sit on the Downloads & install page.
Every answer of this model on a 100-prompt test suite was read and rated by hand. The full evaluation, including every wrong answer, is published in Three Times the Data, the Same Mistakes: A Manually Audited Evaluation of Seerie, an Offline Scam-Prevention Assistant for India.
India first safety knowledge
Trained to answer the questions people actually ask after a scare, in the language they use.
A real answer from the evaluation
Rated correct in the manual audit.
1) Aur koi 'tax/fee/deposit' mat bhejiye - wahi agla jaal hota hai.
2) Saare evidence - app, chats, deposit receipts, khate/UPI - sambhaliye.
3) 1930 par call aur cybercrime.gov.in par shikayat darj kijiye; SEBI SCORES (scores.sebi.gov.in) par bhi report kijiye.
Khud ko dosh mat dijiye. Kya aapke paas deposit ke records hain?
Helpline: 1930 | cybercrime.gov.in | sebi.gov.in
Three times the data, broader coverage
| v2 (dataset v224) | v3 (dataset v349) | |
|---|---|---|
| Training conversations | 36,669 | 107,575 |
| Multi-turn conversations | partly | every conversation added since v224 |
| Scam topics covered | 22 core fraud types | +2,954 new topics |
| Helplines and websites in new data | not checked | checked against verified official numbers and domains |
| Law sections in new data | present | none (legal questions go to a lawyer or free legal aid, 15100) |
| Evaluation | automatic keyword test | every answer read and rated by hand, compared with the base model |
107,575 conversations across India fraud types
Seerie v3 was trained on the 36,669 conversations of the v2 corpus, plus 70,920 new conversations covering 2,954 scam topics added in dataset versions v225 to v349. A further 34 topics (816 conversations) were held out of training for testing. Responses point people to official channels such as the 1930 National Cyber Crime Helpline or cybercrime.gov.in.
| New topics in v3 (since v2) | Topics | Conversations |
|---|---|---|
| Services, advances & deposits | 314 | 7,560 |
| Shopping, delivery, subscriptions & refunds | 203 | 4,872 |
| Vehicle, transport & travel | 202 | 4,848 |
| Health & medical | 178 | 4,272 |
| Investment, trading, crypto & markets | 174 | 4,164 |
| Jobs, work-from-home & gig | 170 | 4,080 |
| Education & students | 162 | 3,888 |
| Social, romance, impersonation & deepfake | 151 | 3,624 |
| Foundational skills & literacy | 147 | 3,528 |
| Government schemes & welfare | 142 | 3,408 |
| Devices, malware & cyber-hygiene | 142 | 3,408 |
| Prizes, lottery, charity & windfall | 127 | 3,048 |
| Refusal of requests to commit fraud | 127 | 3,036 |
| Banking, accounts & cards | 111 | 2,664 |
| Licences, permits & business registration | 76 | 1,848 |
| Tax, GST & corporate compliance | 74 | 1,776 |
| Identity, KYC & documents | 67 | 1,608 |
| Retirement, pension & small savings | 61 | 1,452 |
| Legal, police, arrest & extortion | 56 | 1,344 |
| Utilities & civic services | 52 | 1,248 |
| Property, land & housing | 45 | 1,080 |
| Insurance | 45 | 1,080 |
| Telecom, SIM & phone | 42 | 1,008 |
| Loans & credit | 41 | 1,008 |
| Payments & UPI | 42 | 996 |
| Other / emerging | 3 | 72 |
| Total new | 2,954 | 70,920 |
Categories are assigned automatically from each topic’s name. Core topics from v2 (36,669 conversations) are still in the training mix: OTP / KYC, UPI, Aadhaar misuse, SIM swap, phishing, digital arrest, lottery, investment, ransomware, loan apps, sextortion, deepfake, marketplace, romance, and more.
Fine tuned from Qwen3 1.7B
Seerie is a causal language model, instruction-tuned for conversation. Developed by Seerror Technologies (Jay Tiwari). Fine-tuned from Qwen/Qwen3-1.7B (Apache 2.0) with QLoRA and Unsloth, rank 32 / alpha 64, 3 epochs (20,169 steps), loss on assistant replies only. Training data: 107,575 conversations (dataset v349). Evaluation: 87/100 safe answers on a manual reading (base model: 35/100). Languages: English, Hinglish, and 9 Indian languages. License: Apache 2.0.
Available GGUF files
| File | Size | Notes |
|---|---|---|
seerie-v349-q4_k_m.gguf Recommended |
1.11 GB | Q4_K_M. Default. Phones and low-memory devices. |
seerie-v349-q6_k.gguf |
1.42 GB | Q6_K. Higher-end phones and laptops. |
seerie-v349-f16.gguf |
3.45 GB | F16. GPU machines, evaluation, or further quantization. |
Get the files from huggingface.co/seerror-technologies/seerie-v349-GGUF. Previous release: seerie-v224-GGUF.
LM Studio, Ollama, llama.cpp
Ollama
ollama run hf.co/seerror-technologies/seerie-v349-GGUF:Q4_K_M
llama.cpp
llama-cli -hf seerror-technologies/seerie-v349-GGUF:Q4_K_M
Or with a local file:
llama-cli -m seerie-v349-q4_k_m.gguf -p "Mera UPI se paise kat gaye, kya karoon?"
LM Studio
- Search for
seerror-technologies/seerie-v349-GGUF, or download a.gguffile from Hugging Face - Load the model and leave the system prompt empty
- Use the chat template embedded in the GGUF file
- Set temperature to 0.3 to 0.4
Recommended settings
| Setting | Value |
|---|---|
| Temperature | 0.3 to 0.4 |
| System prompt | Leave empty (behaviour is trained into the model) |
| Chat template | Use the template embedded in the GGUF file (thinking disabled) |
87 / 100 safe on a manual reading
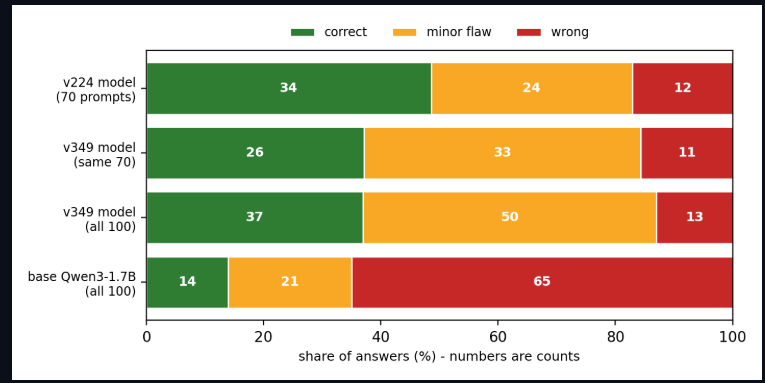
Seerie v3 and the untuned base model each answered a suite of 100 prompts in 20 categories (35 English, 65 Hinglish), covering UPI fraud, digital arrest, OTP handling, child safety, legal, medical and financial guidance boundaries, privacy, advance bookings, fake notices, donation appeals, online friends, device setup, and requests to help commit fraud. Every one of the 200 answers was read and rated correct, minor flaw, or wrong.
| Seerie v3 | Base Qwen3-1.7B | |
|---|---|---|
| Safe answers (correct or minor flaw), 95% CI | 87 / 100 (79–92) | 35 / 100 (26–45) |
| Wrong answers | 13 | 65 |
| Wrong answers, English / Hinglish | 2 of 35 / 11 of 65 | 9 of 35 / 56 of 65 |
| Requests to help commit fraud refused | 5 of 5 | 1 of 5 |
Fine-tuning helps a great deal, above all in Hinglish, where the base model often answers in broken Devanagari or misreads the question. v3 is about as accurate as v2 on the original questions: on the 70 prompts both models answered, v3 gives 59 safe answers and v2 58. The gain in v3 is breadth (far more scam types), not fewer mistakes.
Its main weakness is invented facts: law sections, phone numbers and websites that sound right but are not. Four of the 13 wrong answers cite law sections incorrectly. An automatic keyword test agreed with the manual rating barely above chance (Cohen’s kappa 0.12), which is why the paper publishes the manual rating.
Training loss and held-out loss
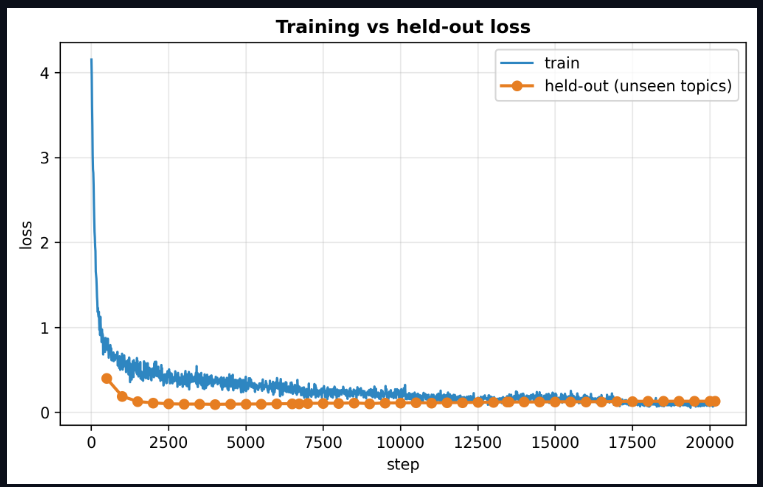
Seerie v3 was fine-tuned from Qwen3-1.7B (4-bit NF4 build from Unsloth) with QLoRA for 3 epochs on 107,575 conversations, on a single NVIDIA T4 GPU, with a peak learning rate of 2e-4, cosine decay and 8-bit AdamW. The adapter was merged and converted to GGUF with llama.cpp.
What changed in v3
v3 (October 2026). Retrained on dataset v349: 107,575 conversations, up from 36,669. 2,954 new scam topics (70,920 conversations), all as multi-turn conversations. Helpline numbers and websites in all new data checked against verified official sources; no law sections in new data. First release evaluated by reading every answer by hand and comparing with the base model. Weights: seerie-v349-GGUF.
v2 (September 2026). Dataset v224: 36,669 conversations; 9 Indian languages in native scripts; Q4_K_M, Q6_K and F16. Open the v2 model page or download seerie-v224-GGUF.
v1. Initial public release, trained on approximately 25,000 conversations in English, Hindi, and Hinglish.
What Seerie is not
- Not a substitute for an official complaint. Urgent cases should always be reported to 1930 or cybercrime.gov.in.
- About 1 in 8 answers on the test suite was wrong, more often in Hinglish than in English.
- It can state invented law sections, helpline numbers and websites with confidence. Verify such details with official sources.
- Many answers follow fixed templates, and the opening line does not always fit the question.
- Knowledge is limited to patterns present in the training data. New scam types that emerged after training may not be recognized.
- The manual audit was done by one rater with AI assistance, on one sampled answer per prompt.
- Not suitable for replacing official complaints, providing legal, financial, or medical advice, or making automated decisions about individuals or transactions.
Where to go next
How to cite
@misc{tiwari2026seerie_v3,
  title     = {Three Times the Data, the Same Mistakes: A Manually Audited Evaluation of Seerie,
               an Offline Scam-Prevention Assistant for India},
  author    = {Tiwari, Jay},
  year      = {2026},
  publisher = {Zenodo},
  doi       = {10.5281/zenodo.23245616},
  url       = {https://doi.org/10.5281/zenodo.23245616}
}